Products & tools · first seen 15 Sep, updated 15 Sep
Optimizing cost and latency with Amazon Bedrock prompt caching
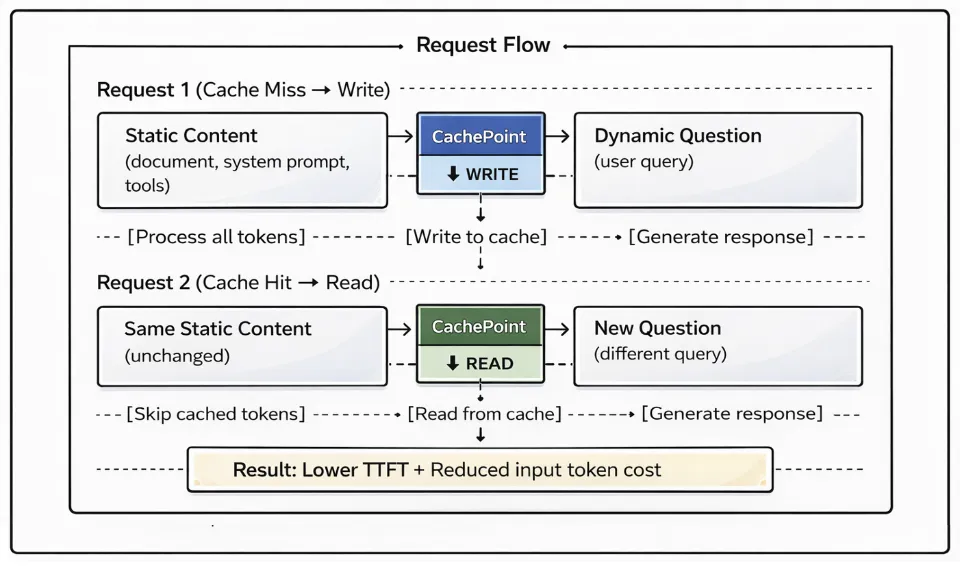
Prompt caching in Amazon Bedrock can cut input token costs by up to 90% when you repeatedly send the same context to foundation models. This post walks through six practical prompt caching scenarios using the Converse API: message content,…
Summary from AWS Machine Learning Blog.
Coverage 1 article · 1 outlet
-
AWS Machine Learning BlogOptimizing cost and latency with Amazon Bedrock prompt caching