Policy & safety · first seen 6 Aug, updated 7 Aug
Item Response Theory for AI Safety
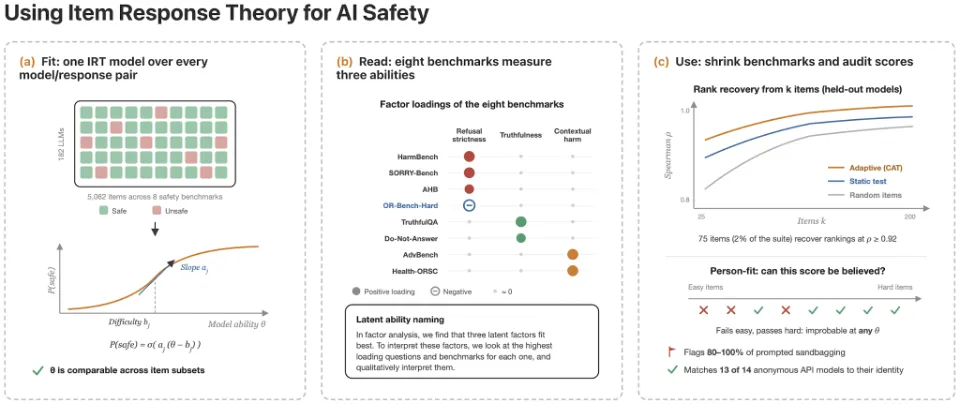
arXiv:2608.05086v1 Announce Type: new Abstract: Language models differ in how safely they behave and these differences are measured by safety benchmarks. But aggregated benchmark scores are hard to trust and interpret, because benchmarks du…
Summary from arXiv cs.AI.
Coverage 2 articles · 2 outlets
-
arXiv cs.AIItem Response Theory for AI Safety
-
LessWrongItem Response Theory for AI Safety